Map data credits
OpenFreeMap © OpenMapTiles Data from OpenStreetMap
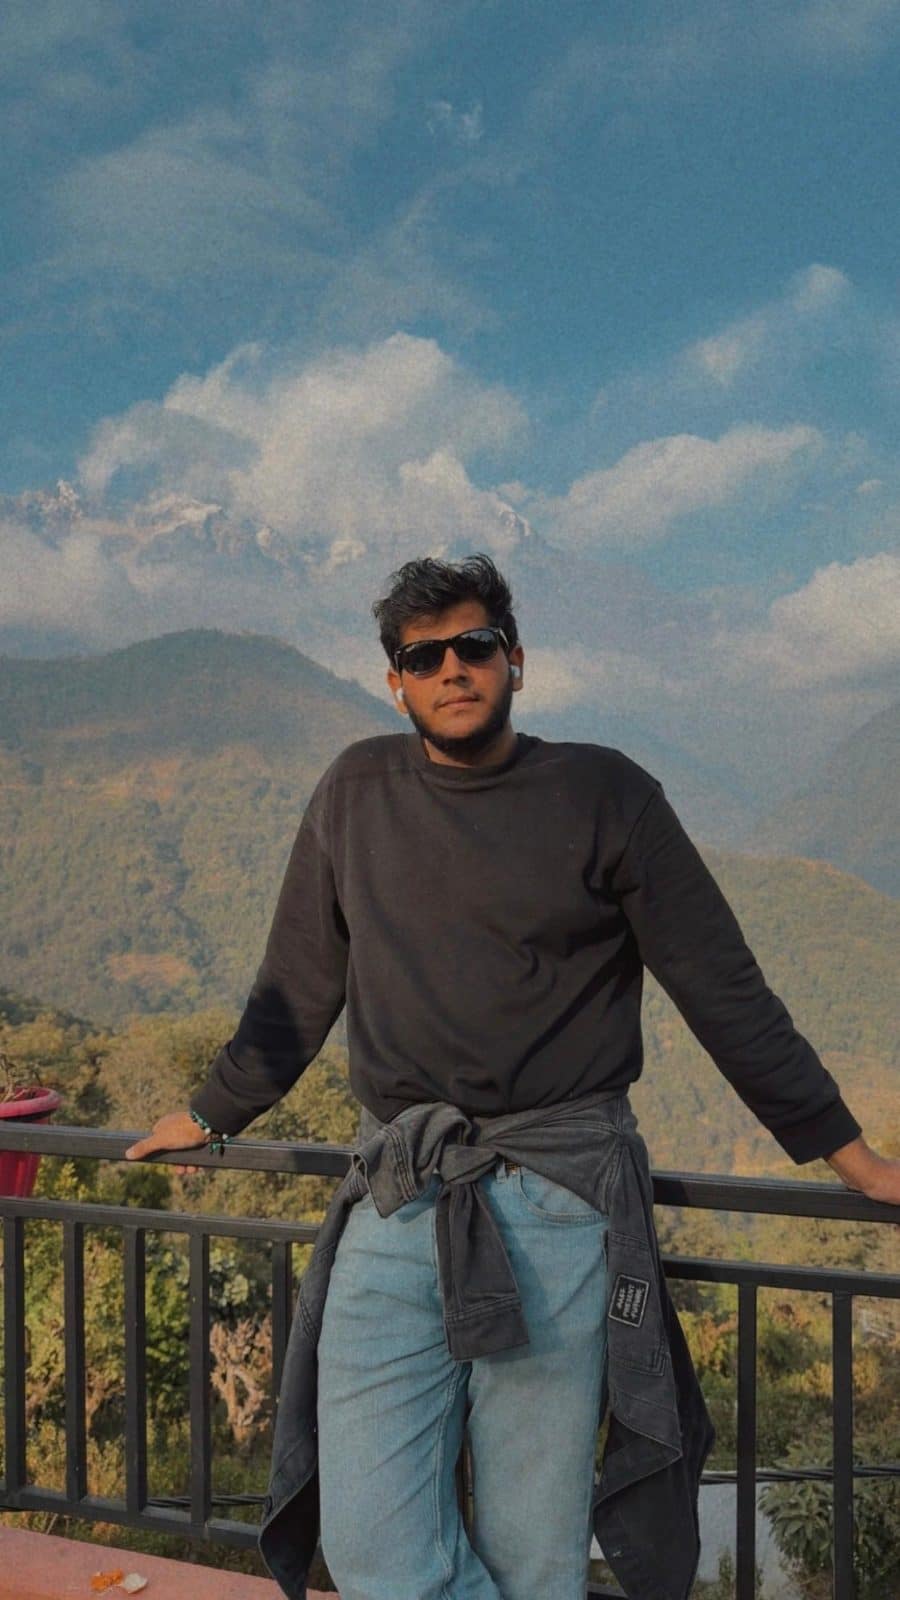
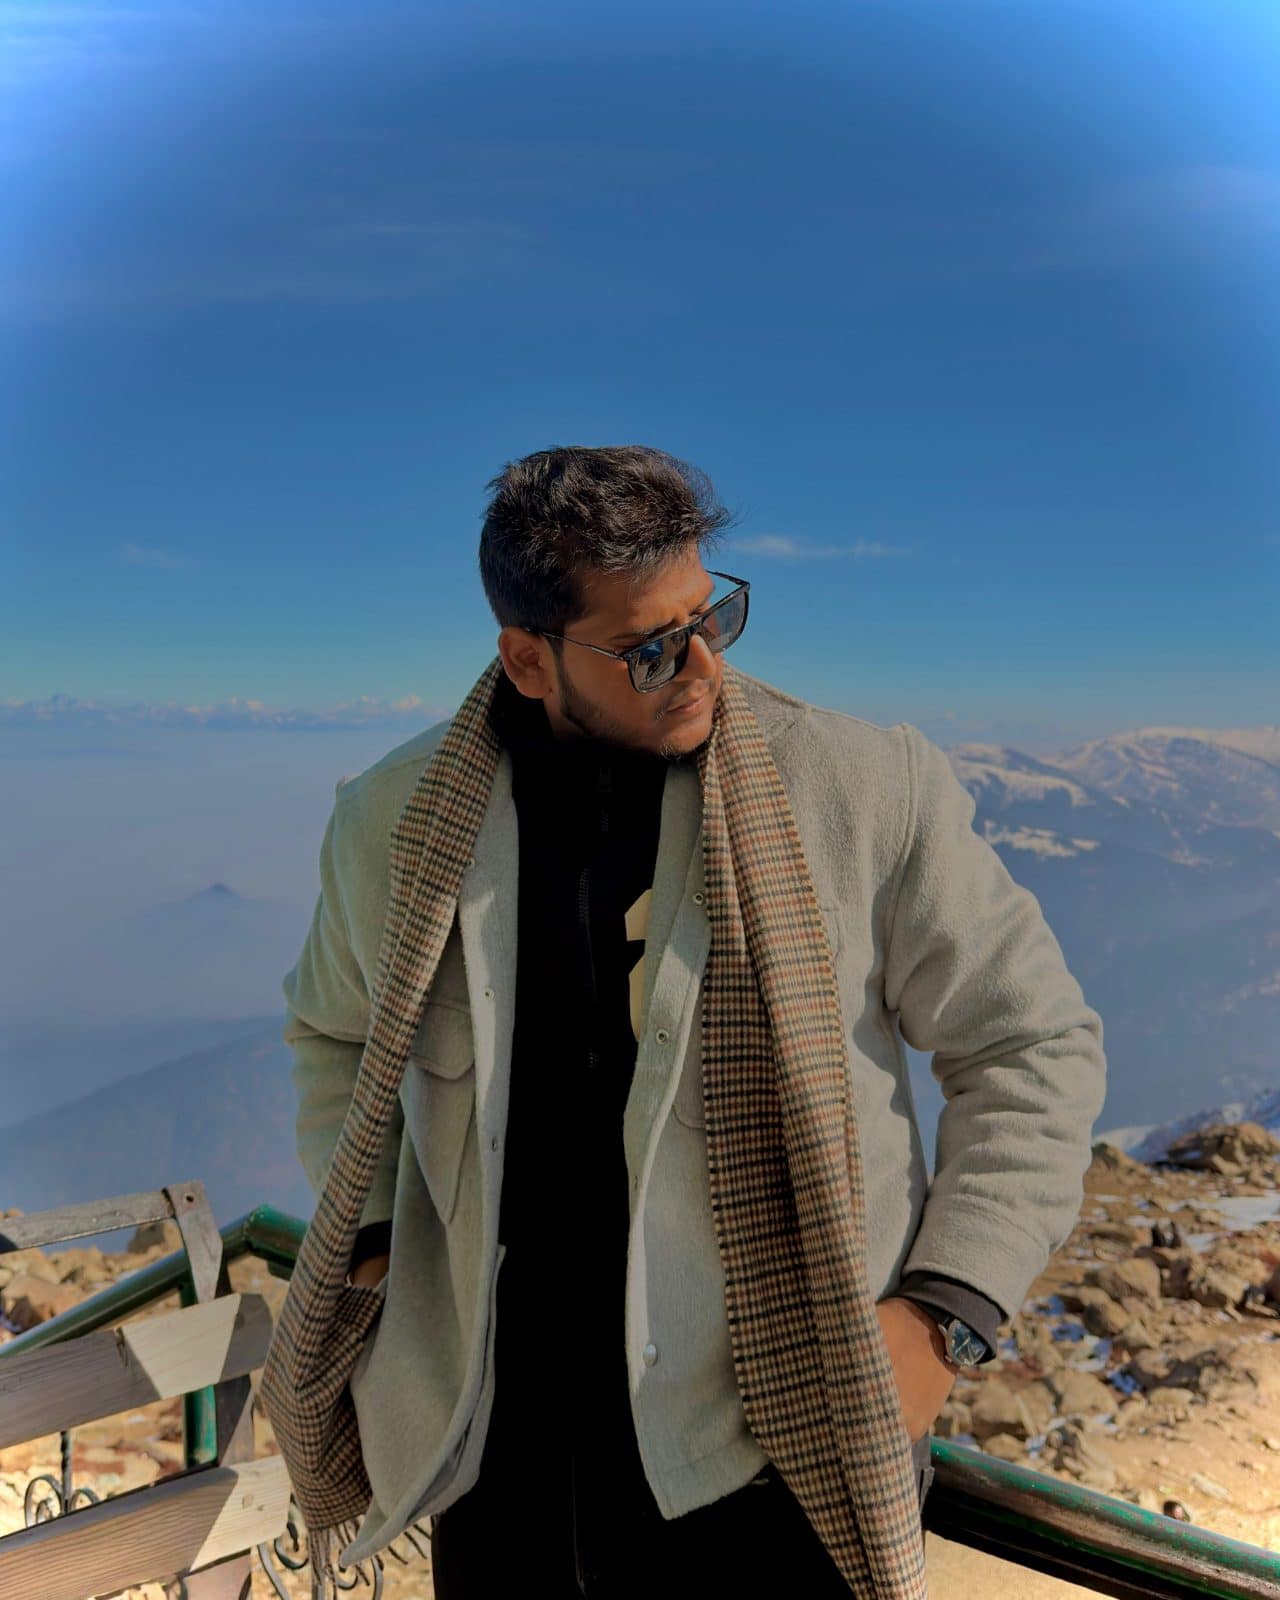
Close up
Photo 1 of 14: Close-up of Sahil Bansal in sunglasses and a rust-coloured shirt, in dappled light
hi, sahil here. 👋Sahil Bansal, DevOps, Cloud and Infrastructure Engineer
yo DevOps, cloud & infrastructure engineer from India 🇮🇳
I build cloud systems that don't break at 3am. From zero-downtime migrations to cost-optimized infrastructure. I obsess over reliability, automation, and giving teams the confidence to deploy. Most recently architected scalable infrastructure at Buyogo AG through June 2026 — currently open to new opportunities.
$ current-stack

CHAPTER 01 · THE PERSON
I build the platforms other people's code runs on, quietly, so they never become the story.


why devops?
My journey, philosophy, and what drives me
Frictionless Deployments
I fell in love with DevOps when I realized deployments were the invisible bottleneck. Teams shipped code, but getting it to production safely and reliably was where the real problem lived. I became obsessed with removing that friction—building systems where infrastructure gets out of the way so engineers focus on shipping.
Boring Infrastructure
I believe infrastructure should be boring. Not in a boring-as-in-uninteresting way, but in a boring-as-in-it-just-works way. No surprises at 3am. No manual firefighting. Systems designed with reliability and automation at the core.
Faster Than Light
Sub-minute feedback loops, automated canary deployments, and reproducible artifacts. Scaling happens invisibly, and telemetry tells the story of what's happening before it becomes a problem.
Reliability at Scale
I'm passionate about infrastructure that's reproducible, observable, and cost-conscious. I love solving problems that have scale (500+ users, millions of requests) where resilience under pressure matters.
Operational Excellence
I value teams that care about operational excellence and aren't afraid to question "the way we've always done it." Building transparent, automated pipelines where engineers ship with confidence and shared ownership.
CHAPTER 02 · THE ROAD
None of it came from a course. It was learned on the job, with real traffic, real pagers and real deadlines.
experience
Where I have worked and what changed because of it.
Software Engineer — DevOps & Cloud Infrastructure
Jun 2024 – Jun 20262 yrs 1 moArchitected a 99.99% available multi-tenant FTP ingress platform (500+ merchants) using SFTP-gateway and automated AWS provisioning
- Led ClickOps → Terraform migration + CI/CD modernization (GitHub Actions, semantic versioning), reducing TTR by 40% and improving engineering velocity by 30%
- Drove reliability + cost outcomes: 40% AWS spend reduction (~$40k/yr), stronger observability (Prometheus/Grafana), real-time ELT (Dagster/DLT/ClickHouse; minutes → ms), and zero-downtime Auth0 migration for 1,000+ users
- AWS
- Terraform
- GitHub Actions
- Prometheus
- Grafana
- Dagster
Workflow Automation Engineer - Freelance
Mar 2026 – Apr 20262 mosDesigned and deployed ZabeSync: an end-to-end LinkedIn content automation pipeline (n8n on AWS EC2, Docker) with Discord as the human-in-the-loop control plane
- Built AI-assisted daily ideation + research workflows with deduped content delivery via Discord and asset storage in Google Drive
- Implemented draft → one-click publish by integrating LinkedIn API with Supabase-backed state (idempotency, workflow state, deduplication), unifying Discord/Drive/LinkedIn into one orchestration system
- n8n
- AWS
- Docker
- Discord
- LinkedIn API
- Supabase
Analyst Trainee — Cloud & DevOps
Jan 2024 – Jun 20246 mosRefactored monolithic CI/CD pipelines into modular stages, increasing success rates by 15%
- Integrated Prometheus alerting with Slack, reducing incident response time by 20%
- Prometheus
- Slack
Software Engineer — DevSecOps
Jun 2023 – Nov 20236 mosEmbedded security gates in AWS CodeBuild, preventing 95% of critical CVEs
- Migrated logging storage to AWS EFS, improving query performance by 30%
- AWS
- CodeBuild
- EFS
Software Engineer Intern
Jun 2022 – Jul 20222 mosAutomated CI/CD workflows in Azure DevOps and improved front-end performance using ReactJS
- Azure DevOps
- React
CHAPTER 03 · THE WORK
Here is what that looked like once it shipped.
featured projects
Infra and automation work I ship.
Automation & AI
LumaCV: AI Resume Intelligence
Open-source AI resume platform with anti-hallucination fact validation, deterministic ATS scoring, and native Typst PDF typesetting.
- AI/LLM
- Next.js
- Rate Limiting
- Supabase
- +4
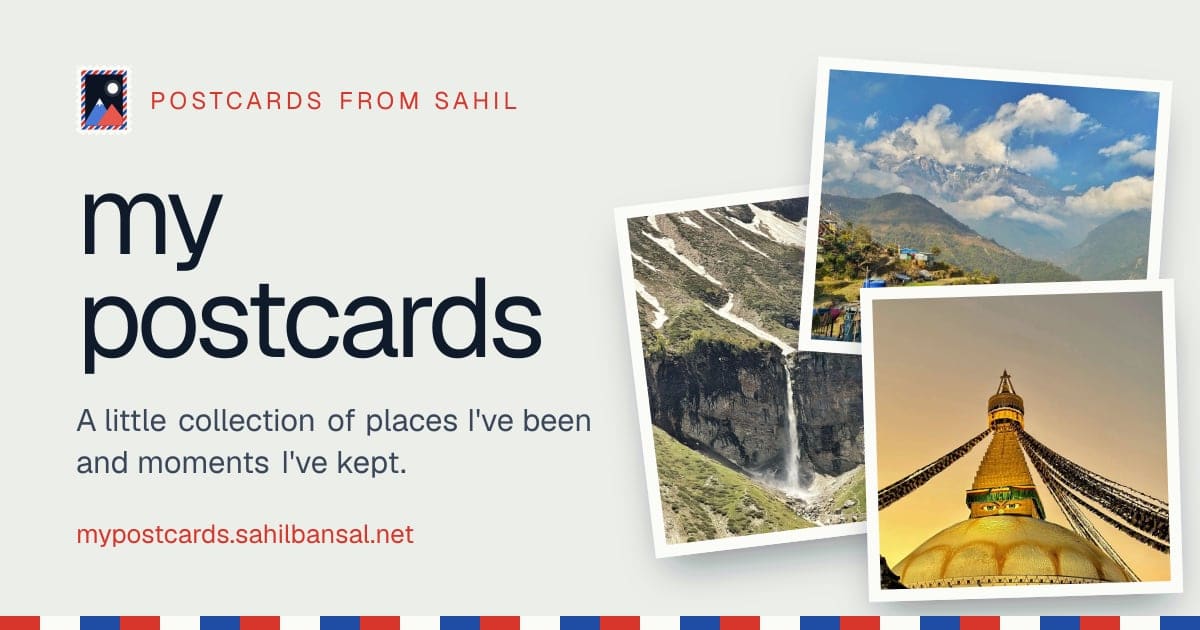
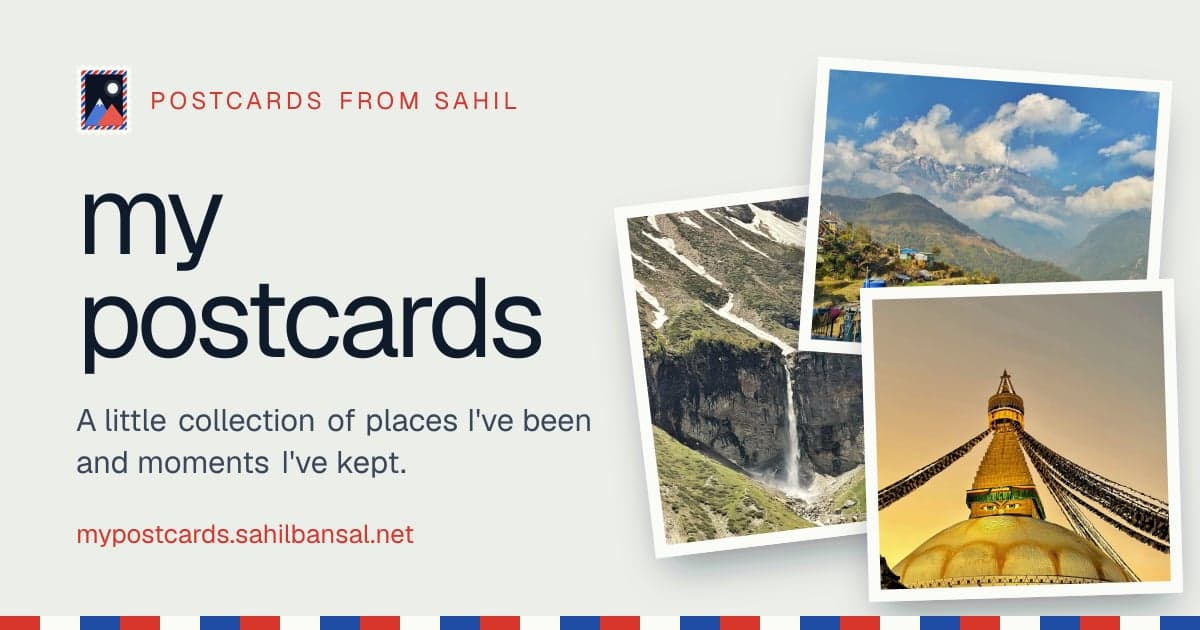
A photo-first travel and café journal: 282 postcards as files in the repo, validated at build, mapped from their own GPS and prerendered as 665 static pages.
- CSS Modules
- MapLibre
- Next.js 16
- React 19
- +4
cloud architecture & systems
How the multi-tenant merchant platform handles a request, and how a change gets to production safely.
Step 1 of 6
Follow one merchant request from the edge to the metrics that watch it.
Merchant Clients
Ingress Traffic · TCP:22 / HTTPS:443
100%
Tenant Isolation
The problem
500+ independent merchants requiring isolated credential boundaries, private directory trees, and zero cross-tenant visibility.
What I built
Per-tenant chroot directory containment with automated credential rotation managed through Terraform and AWS Secrets Manager.
- 500+ Tenants
- SFTP Clients
- REST Consumers
transfer-family.tf
resource "aws_transfer_user" "merchant" {
  server_id      = aws_transfer_server.sftp.id
  user_name      = each.key
  role           = aws_iam_role.sftp_tenant.arn
  home_directory = "/bucket/tenants/${each.key}"
}
CHAPTER 04 · THE CRAFT
Behind every project is a toolbox, and a few defaults I keep until the problem says otherwise.
skills & expertise
Technologies and tools I work with, by area.
skill dependencies
How the skills fit together, at a glance. Select anything to explore it.
The toolchain
Terraform, Kubernetes, GitHub Actions and Prometheus do the heavy lifting, each wired into production work. Terraform: Infrastructure as Code Migration, Multi-Tenant Merchant Platform.
Most connected skills
Ranked by how many other skills each one links to on the map. AWS sits at the centre of most of them.
engineering philosophy
Defaults I reach for until the problem demands otherwise.
Stateless by Default
Push state to databases, caches, object stores. Compute is cheap; state is a liability.
Design for Failure
Retries, circuit breakers, graceful degradation. If it can't survive a node down at 3 AM, it's not prod-ready.
Observability > Monitoring
Monitoring says it's broken. Observability says why. Structured logs, traces, SLI-driven alerts.
IaC or It Didn't Happen
Not in version control? Doesn't exist. Terraform for infra, Actions for pipelines, PRs for changes.
CHAPTER 05 · THE PROOF
Don't take my word for it. Here is what the people I worked with say, and what is on record.
what people say
Recommendations from managers, colleagues and collaborators.
“Sahil is a sharp, highly effective Automation Engineer whose work with n8n has been instrumental in streamlining our operations at Zabe. He possesses a deep understanding of complex workflow logic, API integrations, and data routing, transforming manual, time-consuming bottlenecks into reliable, automated pipelines. Beyond his technical command of n8n, Sahil approaches architecture with scalability and error-handling in mind—ensuring critical synchronization flows run smoothly under pressure. He is proactive, quick to troubleshoot edge cases, and consistently delivers solutions that save engineering hours and operational overhead. Sahil would be an outstanding asset to any team looking for a dependable engineer to build robust, scalable integrations and workflow infrastructure.”
Yash GargFounder @ Zabe.in
“I worked with Sahil at Buyogo. He is an exceptional engineer who takes the lead of delivering features and owning them at an exceptional quality, along with his versatility of helping across the engineering org. He is well talented with Java, Terraform and AWS.”
Manhal RahmanSDE II @ Amazon
“I've worked closely with Sahil and found him to be a reliable, impact-driven DevOps engineer. He took strong ownership of cloud and infrastructure challenges, improved system reliability, and drove meaningful automation and cost optimizations in AWS. Sahil's technical depth and proactive mindset made him someone I could trust with critical systems.”
Taylan KutayFounder of relyd (Cloud ERP for SMEs)
“I worked with Sahil as a Devops Engineer and had a good experience collaborating with him. He handled day-to-day tasks well, supported deployments, and optimised the architecture to reduce cost without reducing the throughput and availability of the system. He was dependable, easy to work with and responsive whenever issues came up. His practical approach and willingness to help the team was top notch. His ownership over the infrastructure of the project helped keep things running smoothly. I'd recommend him as a reliable Devops Engineer and teammate.”
Arshaque MohammedSenior Software Engineer at JPMorganChase
certifications
Professional certifications and credentials.
Amazon Web Services (AWS)
DevOps on AWS Specialization
Issued February 2024
Credential IDLF56PF27EJDYShipping software on AWS: CI/CD pipelines, infrastructure as code and monitoring.
Verify on coursera.org(opens in a new tab)Postman
Postman API Fundamentals Student Expert
Issued July 2024
Credential ID66a32c7bb1bbd519a44e70c0API fundamentals: sending requests, writing tests and documenting APIs in Postman.
Verify on badgr.io(opens in a new tab)Atlassian
Agile with Atlassian Jira
Issued January 2024
Credential ID93BY9N49MRUARunning agile work in Jira: backlogs, sprints, boards and workflows.
Verify on coursera.org(opens in a new tab)
CHAPTER 06 · IN THE OPEN
The rest happens in public: commits, posts, and a terminal you can poke at.
$ git log --since="1 year ago"
shipping cadence
A year of GitHub activity, live from my profile. Flip it flat for the classic heat map, or drag the skyline to orbit.
recent posts
- Your pipeline has more access than any engineer on your teamOct 8, 2026
- The frontend is not a security boundaryAug 21, 2026
CHAPTER 07 · YOUR TURN
That is the story so far. Ask the terminal anything, or just say hello.
explore by terminal
Prefer a prompt? Open the terminal and try help, whoami or route argocd.
A read-only shell over this portfolio: cd into projects and articles, cat a case study, grep across everything, or neofetch for what this site is built with.